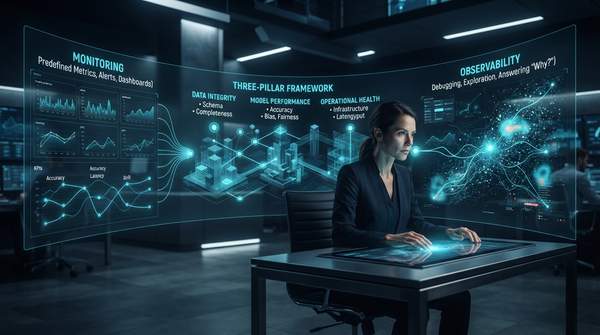
Model monitoring and observability are the practices that keep a machine learning system trustworthy after deployment, and they are not the same thing. Monitoring is the narrower discipline: it tracks predefined metrics and alerts you when something crosses a threshold. Observability is the broader capability: it gives you enough recorded context—metrics, logs, and traces—to diagnose why something went wrong. A practical MLOps monitoring strategy splits the work into three pillars: data integrity and drift, model performance, and operational health, each with its own failure modes and its own metrics.
Understanding ML Model Monitoring and Observability
Practitioner guides describe monitoring as a subset of observability. Monitoring answers "is the system behaving as expected right now?" by watching chosen indicators against preset alert thresholds. Observability answers "why did it deviate?" by combining quantitative metrics with logs and traces into a comprehensive view of system health, performance, and behavior. Writing on observability in MLOps, Ola Sapa identifies metrics, logs, and traces as the three foundational components, with metrics covering model accuracy, latency, throughput, error rates, drift scores, and resource utilization.
The distinction matters operationally. A monitoring dashboard can tell you that accuracy dropped three points overnight; only an observable system lets you slice predictions by feature values, inspect drift contributions, and locate the failing segment. The MLOps principles collected at ml-ops.org frame model monitoring as a continuous process whose elements and strategy should be identified before reaching production, not improvised after an incident.
MLOps Monitoring Framework: Pillars, Problems, and Metrics
The table below organizes production ML monitoring into three pillars. For each, it lists the problems to detect and the concrete metrics used to detect them, so you can map any symptom you observe back to a category and a measurement.
| Monitoring Pillar | Common Issues | Example Metrics |
|---|---|---|
| Data Integrity & Drift — ensures the quality and consistency of input data, detecting shifts in data distribution between training and production. | Data drift (shifts in input distributions) and concept drift (changes in the input–target relationship) silently degrade performance; outliers may signal corruption or fraud; schema changes can break pipelines. | Population Stability Index (PSI), Jensen-Shannon Divergence (JSD), KL Divergence, Wasserstein Distance; feature drift tracking. |
| Model Performance — tracks the accuracy and effectiveness of predictions in production, crucial for maintaining model quality and business value. | Model decay: predictions degrade over time, often triggered by drift, producing poor business outcomes and negative user experiences. | Accuracy, precision, recall, F1-score, AUC-ROC; fairness metrics; model age/staleness. |
| Operational Health — monitors the infrastructure and system components supporting deployment and execution, giving visibility into the operational status of ML workloads. | Infrastructure failures, resource bottlenecks (CPU, memory, GPU), API service issues, error rates, and broken pipelines disrupt serving and affect availability and reliability. | CPU/memory/GPU utilization, latency, throughput, requests per second, error rates, job completion, execution time. |
Use the framework diagnostically: when a symptom appears, first classify it—input data, prediction quality, or system plumbing—then apply that pillar's metrics to confirm and quantify it. The three pillars deliberately overlap, because a single root cause often surfaces in more than one place.
Pillar 1: Data Integrity and Drift Monitoring
Data drift is a shift in the distribution of input data between training and production; concept drift is a change in the relationship between inputs and the target variable. Both degrade a model silently—the predictions keep arriving, but they are increasingly wrong for current conditions. Acceldata's G. Suma notes that monitoring drift is what tells you a model needs retraining, and lists KL Divergence, PSI, and Wasserstein Distance as the statistical distribution tests that measure these shifts.
Fiddler's documentation describes continuous drift detection using JSD and PSI to identify when models encounter data patterns they were not trained on. Beyond distribution shifts, watch for outliers and anomalies that may indicate data corruption or fraud, and schema changes—a removed or modified column can break the ML pipeline outright. Feature drift tracking ties the abstraction back to specifics: it follows changes in individual input features that may cause a decline in prediction accuracy.
Pillar 2: Model Performance Monitoring
Performance monitoring measures whether the model's predictions are actually correct in production. The core metrics are the familiar evaluation set—accuracy, precision, recall, F1-score, and AUC-ROC—but applied continuously rather than only at validation time. New Relic's guidance, drawing on best practices from Daniel Jeffries of the AI Infrastructure Alliance, recommends choosing metrics that align with business objectives and explicitly adding concept drift detection and fairness metrics to the traditional evaluation set, with real-time monitoring to detect issues and respond promptly.
Performance decay is the expected failure mode here: older models tend to decay as production data diverges from training data, which is why the ml-ops.org principles recommend measuring the age of the model as a monitored quantity in its own right. The practical challenge is that quality metrics often depend on ground-truth labels, which arrive late or never. Evidently's monitoring guidance acknowledges this trade-off: with labels you can evaluate quality directly, but when a drop appears you still need the supporting metrics to identify the reasons and decide how to handle drift—and sometimes monitoring data drift is the better choice even when labels are available.
Pillar 3: Operational Health Monitoring
Operational health covers everything that is not the model itself but that must work for the model to serve predictions: hardware, services, and pipelines. An MLOps coding course by Médéric Hurier (Fmind) defines infrastructure monitoring as continuously tracking CPU, memory, and GPU utilization, which provides visibility into the operational health and stability of the pipeline from training through inference. Palo Alto Networks' MLOps guide adds that monitoring should track infrastructure status and flag broken pipelines before silent failures reach downstream systems.
The metrics depend on the serving pattern. For batch jobs, execution time and job completion suffice. For an API-served model, Evidently recommends instrumenting the service to collect event-based metrics in real time: total model calls, requests per second, and error rates. Resource metrics like GPU memory allocation, network traffic, and disk usage also feed cloud cost estimation, per the ml-ops.org principles. Alert on both fast spikes and slow drifts, since a gradual resource leak is as damaging as a sudden outage.
Translating Monitoring Alerts into Action
Monitoring only pays off when alerts trigger a defined response. The first step is setting alerting thresholds in advance—ml-ops.org's principles call for pre-setting thresholds on the performance of code, data, and model versions before production. When an alert fires, the goal shifts from detection to diagnosis, and this is where observability earns its keep: Fiddler's documentation describes root cause analysis through feature impact analysis, drift contribution metrics, and data segment performance comparisons, enabling targeted improvements rather than guesswork.
The remediation depends on the pillar. Data issues may call for fixing upstream pipelines or rejecting flawed inputs—Palo Alto Networks suggests using thresholds to auto-reject data with nulls, leakage, or poor accuracy before it moves downstream. Confirmed drift or decay points to retraining, since drift monitoring exists precisely to identify when a model no longer reflects current conditions. Operational alerts point to infrastructure adjustments: scaling resources, restarting services, or repairing pipelines. Evidently frames the overall goal plainly: monitoring should give confidence that the system is running well, and in the event of failure, the extra metrics provide the context needed to diagnose and solve the problem.
Monitoring for Regulatory Compliance and Ethical AI
A monitoring system is also the evidentiary backbone for governance. New Relic notes that in regulated industries, monitoring helps ensure a model complies with legal and ethical standards and assists in maintaining transparency and accountability. Sapa's observability guide makes the audit dimension explicit: maintaining detailed records for audits, explainability, and governance requirements is a core component of MLOps observability.
Ethical obligations extend beyond record-keeping. Singapore's national MLOps Playbook recommends that monitoring platforms help test for unwanted biases in model outputs—for example, performance differences across demographic groups—and identify potential adversarial threats, with some tools able to flag data drift that might indicate an adversarial attack. Fiddler's documentation ties the threads together: effective observability lets teams detect issues early, maintain regulatory compliance, and provide governance for responsible AI. Fairness metrics belong in the performance pillar precisely because bias is a performance failure concentrated in a segment, invisible in aggregate accuracy.
Actionable Insights: From Alerts to Continuous Improvement
Implement a structured MLOps monitoring strategy that covers data, model, and operational health, and establish clear protocols for translating monitoring alerts into corrective actions like model retraining or system adjustments. Decide the strategy before production: identify the elements to monitor, pre-set alert thresholds, and ensure the metrics, logs, and traces exist to support root cause analysis when an alert fires.
The measurable indicator of success is a decrease in the time taken to detect and resolve critical model failures or performance degradation incidents, coupled with improved traceability for regulatory audits. Track detection-to-resolution time as an explicit metric, and treat audit traceability as a testable property: when a regulator or reviewer asks why a model behaved as it did on a given date, your monitoring records should answer the question without reconstruction.
Sources
- ML OPS
- Scaling AI with Confidence: The Importance of ML Monitoring — Acceldata
- ML Observability - Fiddler Documentation
- Model Performance Monitoring with Machine Learning — New Relic
- Monitoring ML systems in production. Which metrics should you track? — Evidentlyai
- 7.6. Infrastructure - MLOps Coding Course
- What Is MLOps? Machine Learning Operations — Palo Alto Networks
- Observability for MLOps — ML Architects
- Chapter 6C: Model Monitoring and Observability Tools - MLOps Playbook — Playbooks