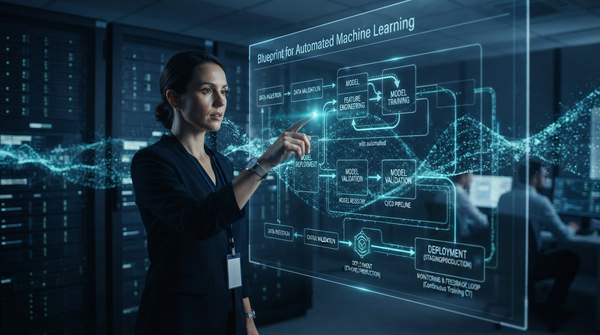
Machine Learning Operations, or MLOps, applies the principles of DevOps to machine learning systems to create automated, reliable, and continuous lifecycles for model development and deployment. A typical MLOps platform architecture is structured to facilitate a continuous workflow that encompasses integration, delivery, and training, moving a model from initial experimentation to production monitoring. This process relies on a set of interconnected architectural components, including source code repositories, feature stores, and orchestration tools, that work together to manage the unique complexities of machine learning, such as evolving data and model performance decay.
Understanding MLOps: Bridging Development and Operations for Machine Learning
MLOps extends traditional software engineering practices by incorporating principles specifically tailored for the data-centric nature of machine learning. While it borrows from DevOps, MLOps introduces unique concepts to handle the challenges of managing not just code, but also data and models as first-class citizens in the development lifecycle. These core practices are often abbreviated as CI/CD/CT.
According to materials from MLOps community resources, these concepts are defined by their specific application to machine learning. Continuous Integration (CI) in MLOps goes beyond testing code; it involves the rigorous testing and validation of data and models as well. Continuous Delivery (CD) focuses on the delivery of an entire ML training pipeline, which in turn automatically deploys the model's prediction service. This ensures that not just the model, but the entire system that produces it, is reliable and deployable.
Unique to MLOps is the concept of Continuous Training (CT). This practice addresses the reality that machine learning models can become stale as new data becomes available. As one MLOps guide explains, CT is triggered "whenever new data is available," initiating an automated process for retraining models that also "includes data and model validation steps." This automated retraining loop is a key differentiator from standard CI/CD pipelines in software development, ensuring models remain performant and relevant over time.
Key Architectural Components of an MLOps Platform
A robust MLOps platform is built from several essential, platform-agnostic components that each serve a distinct function in the automation pipeline. While specific tools may vary, their roles within the architecture remain consistent across different implementations.
-
Source Code Management: Platforms like GitHub act as the central repository for all source code, enabling version control and collaboration. According to Microsoft documentation, this component integrates directly with CI/CD pipelines to trigger automation whenever changes are committed.
-
Feature Store: This is a critical component that acts as a centralized hub for machine learning features. A guide on MLOps describes its goal as processing data from various sources and transforming it into features consumed by both model training and serving. A Databricks blog post emphasizes that a feature store is a "centralized repository that stores and manages features for machine learning models, providing a single source of truth for feature definitions and enabling reuse across multiple projects." This consistency is vital for preventing discrepancies between training and production environments.
-
ML Metadata Store: This component tracks the entire lifecycle of ML experiments. It records information about model runs, parameters, performance metrics, and the lineage of data and models. This tracking is crucial for ensuring the reproducibility of experiments, debugging issues, and maintaining governance over ML assets.
-
CI/CD Orchestration: Tools like Azure Pipelines automate and manage the build, test, and deployment workflows. These systems, as described by Microsoft, break down the end-to-end process into logical steps, or tasks, to ensure consistent and reliable deployment of machine learning solutions.
-
Data Storage: This layer, which can include data lakes, manages the large volumes of structured and unstructured data required for machine learning workflows.
-
Serving Infrastructure and Monitoring: These components provide the environment where the final model is deployed to make predictions. Integrated monitoring tools track model performance in real time, providing feedback that can trigger alerts or automated retraining cycles.
The MLOps CI/CD/CT Workflow: A Continuous Lifecycle
The MLOps workflow automates the machine learning lifecycle through a series of interconnected stages. Each stage involves specific activities and architectural components, with the output of one stage triggering the next in a continuous loop. The process begins with development and experimentation and extends through automated testing, deployment, and ongoing monitoring in production.
The first stage, Development and Experimentation, is where data scientists and ML engineers explore data, develop algorithms, and write the source code for the entire ML pipeline. This includes scripts for data extraction, validation, preparation, model training, and evaluation. The primary output of this stage is source code, which is committed to a version control system like GitHub.
Once code is committed, the CI/CD Pipeline is automatically triggered. The Continuous Integration phase builds the source code and runs a comprehensive suite of tests. Unlike traditional CI, this includes validating the data schemas, checking feature distributions, and evaluating model quality against predefined thresholds. The output is a set of validated and packaged pipeline components, such as executables or container images, ready for deployment.
In the Continuous Delivery phase, the CI/CD orchestration tool automatically deploys the validated pipeline components to a target environment, which could be for staging or production. This step delivers not only the model's prediction service but also the entire ML training pipeline that created it. The result is a fully deployed and operational ML system.
The final stage is Production Monitoring and Continuous Training. The deployed model serves live predictions while its performance is continuously tracked. If monitoring tools detect performance degradation or if significant new data becomes available, the system automatically triggers the Continuous Training process. This initiates a new run of the entire ML pipeline, starting with retraining the model on the new data, followed by validation and redeployment, thus completing the automated lifecycle.
MLOps CI/CD/CT Workflow Stages and Components
The MLOps workflow automates the machine learning lifecycle through a series of interconnected stages. Each stage involves specific activities and architectural components, with the output of one stage triggering the next in a continuous loop.
| Workflow Stage | Core Activities | Key Components Involved | Output / Next Stage Trigger |
|---|---|---|---|
| 1. Development & Experimentation | Data scientists develop ML algorithms, experiment with different models, and write the source code for data extraction, preparation, training, and evaluation pipelines. | Source Code Management, Feature Store, ML Metadata Store | Source code for models and pipelines is committed to the central repository. |
| 2. Pipeline Continuous Integration (CI) | The system automatically builds the source code and runs a series of tests to validate the code, data, and model components. This ensures all artifacts meet quality standards. | CI/CD Orchestration, Source Code Management, ML Metadata Store | Validated and packaged pipeline components (executables, containers) are ready for deployment. |
| 3. Pipeline Continuous Delivery (CD) | The validated pipeline components are automatically deployed to a target environment (e.g., staging or production). This includes deploying the model training pipeline and the prediction service itself. | CI/CD Orchestration, Serving Infrastructure, ML Metadata Store | A fully deployed and operational ML model and training pipeline. |
| 4. Production Monitoring & Continuous Training (CT) | The deployed model serves predictions while its performance is continuously monitored. When new data becomes available or performance degrades, the system automatically triggers the retraining pipeline. | Serving Infrastructure, Monitoring Tools, Feature Store, Data Storage, CI/CD Orchestration | Live model predictions, performance metrics, and an automated trigger to restart the entire workflow with new data. |
Implementing MLOps: A Path to Robust ML Systems
Organizations should adopt MLOps principles and architecture to automate the machine learning lifecycle, ensuring continuous integration, delivery, and training of models. Moving from ad-hoc, manual ML projects to a structured MLOps approach allows teams to build scalable, reliable, and governed systems. By implementing a continuous lifecycle that integrates development with operations, teams can ensure the consistent and high-quality delivery of machine learning models that adapt to changing data and business needs. Successful implementation will be indicated by a reduction in model deployment time, improved model performance consistency in production, and increased reproducibility of ML experiments.