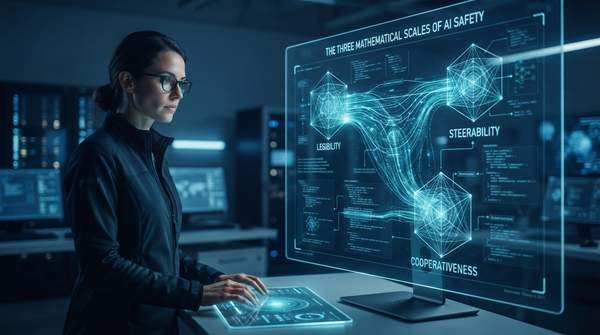
The mathematics being developed to make artificial intelligence safe is best understood as work on three distinct properties, operating at three distinct scales. That is the organizing insight of a September 2026 paper by Cornell mathematician Lionel Levine, who argues that AI safety needs new mathematics targeting systems that are legible, steerable, and cooperative. Legibility concerns what is happening inside a model; steerability concerns what it does; cooperativeness concerns how it interacts with humans and other AIs. This three-scale map gives readers a way to sort the field's technical vocabulary—interpretability, robustness, formal verification, game theory—into goals that are genuinely different, rather than treating "AI safety math" as one undifferentiated research program.
The need for that clarity is real. In Levine's framing, artificial intelligence "threatens to outrun human understanding and control." Current training methods produce systems whose internal reasoning humans, including the engineers who designed them, often cannot follow except by reading the text a model emits while reasoning to itself. Formal verification promises a way around this—mathematical proof rather than intuition—but, as researchers in that area acknowledge, it faces hard practical limits. This article explains the three-property framework, locates the major mathematical approaches within it, and examines where formal verification fits and where it currently falls short.
Introduction to Mathematical AI Safety
Why does AI safety need mathematics at all? Because the alternative is empirical trial and error. If a system's behavior cannot be understood, predicted, or bounded except by observing it, then safety claims are always contingent on the tests that happened to be run. Levine's paper, styled as "an invitation for mathematicians," makes the case that designing AI that humans can understand, control, and cooperate with is a mathematical problem—or rather, a set of problems spread across mathematical fields.
Levine organizes that invitation by field, which is itself revealing about how the field divides. His mapping connects logic and game theory to cooperation; probability to agency and world-models; algebra and representation theory to learned features; and analysis and geometry to generalization and training dynamics. Each section of his paper ends with an open problem accessible to a working mathematician with no prior AI safety experience. In other words, the safety goals are not yet matched to finished tools; they are matched to open research programs.
The point of a scale-based framing is that these goals are not interchangeable. A system could in principle be perfectly legible but badly steerable, or provably well-behaved in isolation but harmful in interaction. Keeping the scales distinct prevents a common conflation, where a success in one area—say, a proof of robustness—is presented as if it settled safety as a whole.
A Framework for Safe AI: Legibility, Steerability, and Cooperativeness
Levine defines the three properties precisely by the scale at which each operates. Legibility concerns an AI system's internal structure: a system is legible to the extent that human researchers and engineers can understand how it represents concepts internally. The subfield that tries to make AI more legible is called interpretability, and it is the mathematical counterpart of the everyday goal of understanding what a model has actually learned.
Steerability concerns behavior—the external actions of the system rather than its internals. The goal here is control: guiding and constraining what the AI does, in the sense of being able to direct its actions toward intended outcomes and away from unintended ones. Robustness fits naturally at this scale as a behavioral property: the system should continue behaving as specified under perturbation or adversarial pressure, not just on the inputs it was tested on.
Cooperativeness concerns interactions, with humans and with other AI systems. Here the goal is alignment in a multi-agent sense: ensuring that an AI's goals mesh with human values and that joint outcomes are beneficial rather than merely individually optimized. Levine's field-mapping points to logic and game theory as the mathematics of this scale—fitting, since cooperation is inherently a property of relationships between agents, not of any single agent in isolation.
What distinguishes these three is the object of intervention. Interpretability research intervenes in representations; control and robustness research intervenes in behavior; cooperative-AI research intervenes in interaction structures. A reader who keeps this distinction can correctly classify most safety techniques on sight.
Categorizing Mathematical Approaches to AI Safety
The table below classifies the core properties and tools discussed across the evidence by scale of application, goal, and mathematical relevance. It is the conceptual map this article is built around: given any safety technique, ask which row it belongs to.
| Property or tool | Scale of application | Goal | Mathematical relevance |
|---|---|---|---|
| Legibility | Internal structure of the AI system | Comprehend the AI's representations and processes; make internals understandable | Interpretability research; algebra and representation theory for learned features |
| Steerability | External behavior of the AI system | Guide and constrain the AI's actions | Behavioral control and robustness |
| Cooperativeness | Interactions with humans and other AIs | Ensure positive multi-agent outcomes and value alignment | Logic and game theory for cooperation |
| Formal verification | Cross-cutting: applies to any safety property that can be specified | Provide formal, verifiable, auditable safety guarantees via mathematical proof | Mathematical proof as a control tool; compositional reasoning |
One clarification the table makes visible: formal verification is not a fourth scale. It is a method that can, in principle, be applied at any of the three—an interpreter's findings about internal structure can be proved, and so can a behavioral robustness property. What varies is whether the property in question has been specified precisely enough to prove anything about.
Formal Verification: Guaranteeing AI Safety with Mathematical Proofs
Formal verification is the most rigorous tool in this landscape because its currency is proof rather than measurement. The "Guaranteed Safe (GS) AI" research program, described in a 2024 paper on arXiv, frames the goal as equipping AI systems with formal, verifiable, and auditable safety guarantees—mathematical proofs that specific safety properties hold, rather than empirical evidence that failures did not appear during testing. On Levine's map, verification operates wherever a safety claim can be stated as a proposition, which is exactly why mathematical proof functions as a tool for controlling AI systems: a proof establishes that certain failure modes are impossible, not merely unobserved.
The GS AI paper identifies a principle that makes this tractable in principle: compositional reasoning. The idea is to construct a proof of safety for an overall AI system by decomposing the top-level proof obligation into sub-obligations on individual components, then verifying each sub-obligation. A system is too complex to prove safe as an undifferentiated whole; components may be tractable. The paper also notes that abstractions that are modular and more interpretable have been found to be easier to analyze with formal verification tools—an unexpected point of contact between the legibility scale and the verification method.
But the same paper flags the catch: not all AI components have formal specifications. Its authors put it bluntly—"we need to do compositional verification without compositional specifications." You cannot decompose a proof obligation when the sub-obligations have not been defined. This is not a bookkeeping inconvenience; it means the proof architecture depends on specification work that, for many learned components, does not yet exist.
A critical analysis posted on the AI Alignment Forum goes further, cataloguing challenges to verification-based approaches and arguing that each challenge corresponds to a hard limitation researchers should expect in practice. Its authors' conclusion is pointed: these challenges "will ultimately be show-stoppers for attempts to use formal verification to produce strong proofs or guarantees against major AI threats in the near-term." Near-term strong guarantees, on this argument, are not merely hard but blocked by structural limitations—among them the difficulty of creating accurate world models against which to verify, and of formulating specifications precise enough to prove against. The honest summary of formal verification's current status is therefore twofold: it is the only approach that offers proof rather than evidence, and it is not currently a near-term solution to major AI threats.
Navigating the Future of AI Safety Through Mathematics
For researchers and practitioners, the practical decision is to develop mathematical frameworks that address AI safety across all three scales—internal legibility, behavioral steerability, and interactional cooperativeness—while treating formal verification as a powerful but specification-limited tool rather than a shortcut around the hard problems.
The three-scale map suggests where effort is thin. Interpretability is younger than behavioral testing; cooperative properties involve logic and game theory that Levine highlights as still largely open; and verification's compositional architecture waits on specifications that do not exist for many learned components.
The measurable indicators to watch are concrete: continued academic publications and research grants focusing on formal methods for AI, advancements in interpretable AI techniques, and new benchmarks for AI alignment and cooperative behavior. Progress on any of these is visible and countable—not a vague sense that safety is improving. Levine's paper is itself a data point on this trajectory: a mathematician with no prior AI safety background, invited in by open problems, published in September 2026. Whether the open problems he lists attract the mathematicians they solicit is the next observable milestone for the framework's own success.