
Embodied Ai
2 articles
Automation & Robotics
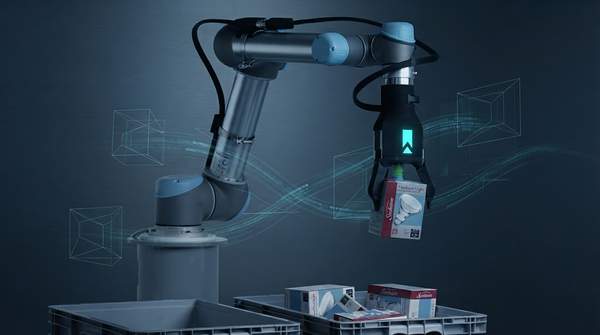
How Vision-Language-Action Models Turn Robot Perception Into Physical Movement
Vision-Language-Action (VLA) models unify perception, language, and action within a single transformer architecture, enabling robots to perform complex physical tasks in unstructured environments. This article explores their architecture, key models, and the challenges and future directions for real-world deployment.
Rui Almeida·October 17, 2026

Explainers
What Is Embodied AI's Role in Future Robotics?
By 2025, the UBTech Walker S1 robot will be adjusting its posture and grip in real-time on Chinese car assembly lines, handling diverse components with a dexterity once thought impossible for...
Meera Iyer·July 21, 2026