Automation & Robotics
How Vision-Language-Action Models Turn Robot Perception Into Physical Movement
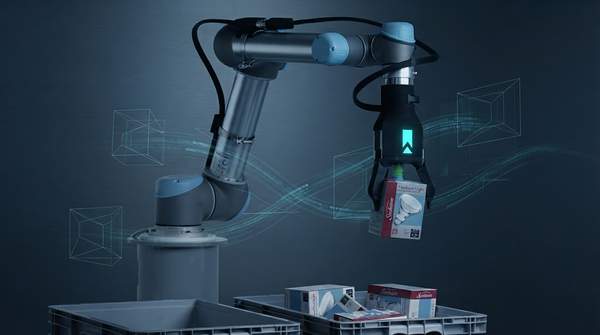
Vision-Language-Action (VLA) models unify perception, language, and action within a single transformer architecture, enabling robots to perform complex physical tasks in unstructured environments. This article explores their architecture, key models, and the challenges and future directions for real-world deployment.
Rui Almeida·October 17, 2026